
More news on this day
A one-millisecond software defect inside the UK’s air traffic control flight-data system triggered a chain reaction that ultimately led airlines to cancel more than 2,000 flights, according to a newly published preliminary report from National Air Traffic Services (NATS).
Get the latest news straight to your inbox!
What happened on September 8 and why it spread nationwide
Published coverage indicates the disruption began on Tuesday, September 8, 2026, when a fault affected NATS’ National Airspace System, the platform that manages flight data used by controllers. While the issue was traced to systems supporting London Area Control, the knock-on effects were felt across the UK network because traffic flow restrictions were needed to keep operations safe while systems were stabilized and flight data was restored.
The preliminary findings describe a failure scenario that unfolded extremely quickly: a routine manual request related to an aircraft code was in process, another higher-priority activity interrupted it, and when processing resumed the defect caused the output to become corrupted. With controllers no longer able to rely on parts of the live flight-data picture, fallback procedures were used while the system was restarted and information reloaded.
NATS’ report indicates that restrictions remained in place for around six hours. Even after operations returned to normal later that day, the wider air-travel system needed time to absorb missed rotations and displaced aircraft and crews, with disruption extending into the following days as airlines rebuilt schedules.
Why a “millisecond” defect can still ground thousands of flights
The headline detail in the report is the timing: the defect is described as occurring “in the space of a millisecond.” In practice, that framing reflects how a tiny timing or sequencing window in complex software can create a rare failure condition that normal operations almost never trigger, yet still produces broad consequences when it does.
In this case, the impact was not limited to one flight plan. Published accounts describe the system producing corrupted data, and the recovery work involving reloading and reconciling flight data so controllers could safely manage traffic volumes again. That sort of restoration is operationally delicate because the airspace system depends on accurate, continuously updated identifiers and routing details.
The preliminary report also points to the reality that modern air traffic management is both highly automated and highly interdependent. A localized technical failure can force a nationwide “rate limit” on departures and arrivals simply because the system is designed to prioritize safety when data integrity cannot be guaranteed.
Passenger impact: cancellations, delays, and a long recovery arc
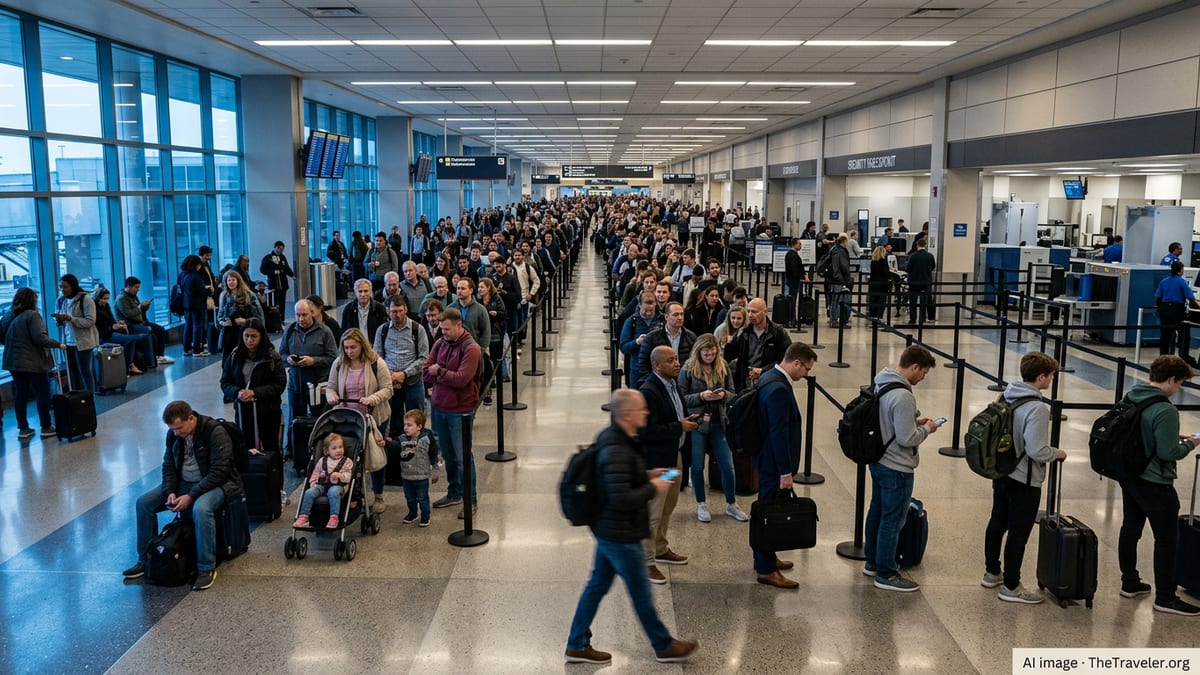
More than 2,000 flights in and out of the UK were canceled, with hundreds of thousands of passenger journeys disrupted, according to the preliminary report and subsequent published coverage. Beyond cancellations, many flights that operated did so under capacity constraints that can amplify delays through the day and into the next, as aircraft and crews end up in the wrong places for later services.
Airlines and airports faced a familiar post-disruption problem: even once airspace restrictions ease, networks must be reset. That can mean rebooking passengers, repositioning aircraft, and finding available crews within duty-time rules, often while airport stands and overnight accommodation are stretched by the sudden volume of displaced travelers.
For travelers, the practical effects are not just time lost at the airport. Missed onward connections, rebooked itineraries that shift by a day or more, and unexpected hotel stays can quickly multiply the disruption beyond the original six-hour constraint described in the report.
Scrutiny intensifies: government-ordered review and accountability questions
The incident has prompted heightened scrutiny of resilience planning and oversight. Published coverage indicates the UK Transport Secretary, Heidi Alexander, ordered an independent review by the Civil Aviation Authority (CAA) to assess NATS’ findings and to examine investment and regulatory accountability related to system resilience.
The disruption also revived broader debate about the robustness of critical aviation infrastructure and whether enough has been done since previous high-profile incidents. NATS has said the latest incident was not connected to earlier outages, but the repetition of major disruptions in recent years has renewed calls for clearer answers about testing, redundancy, and upgrade roadmaps.
While the preliminary report focuses on the technical trigger and immediate operational response, the follow-on work now shifts toward governance: how quickly risks are detected, how thoroughly rare failure modes are tested, and how transparently performance is assessed when a national system failure cascades into mass cancellations.
What affected travelers should know about refunds, rebooking, and care
For passengers caught in the disruption, publicly available guidance from the UK aviation regulator emphasizes baseline protections when flights are canceled. Depending on the circumstances, passengers typically can choose between rerouting on another flight or receiving a refund, and may be entitled to “care and assistance,” such as meals, refreshments, hotel accommodation when necessary, and transport between the airport and lodging.
Because mass disruption can strain airline capacity, travelers often benefit from acting quickly: keeping receipts for reasonable out-of-pocket expenses, checking airline apps for rebooking options, and confirming whether re-routings include partner carriers. When delays extend overnight, accommodation availability near major hubs can tighten quickly.
As the CAA’s independent review proceeds, travelers can expect continued attention on how quickly system failures are communicated, how traffic restrictions are implemented, and whether additional safeguards can reduce the likelihood that a brief software defect results in days of schedule instability.