
More news on this day
A new report into the UK’s latest air travel disruption has concluded the incident was not caused by any incorrect actions by air traffic operators, instead pointing to a technical failure that triggered widespread delays and cancellations across the network.
Get the latest news straight to your inbox!
What the report says happened
Published coverage describes the disruption as stemming from a software defect that affected processing inside the UK’s air traffic system, creating knock-on effects that spread quickly across airports and airline schedules. The preliminary findings also indicate the system’s safety layers worked as intended, even as capacity constraints led to significant operational delays.
The report language drawing attention in travel circles is the conclusion that the disruption was “not caused by any incorrect actions” by operators. That framing matters because it shifts scrutiny toward system design, testing, and change-management rather than individual decision-making in control rooms.
Separate reporting has characterized the defect as extremely brief but impactful, with a timing-related issue described as occurring at the millisecond level. Even small timing defects can be consequential in aviation systems that continuously fuse flight plans, surveillance inputs, and airspace constraints to produce safe routings.
How disruptions cascade from air traffic constraints
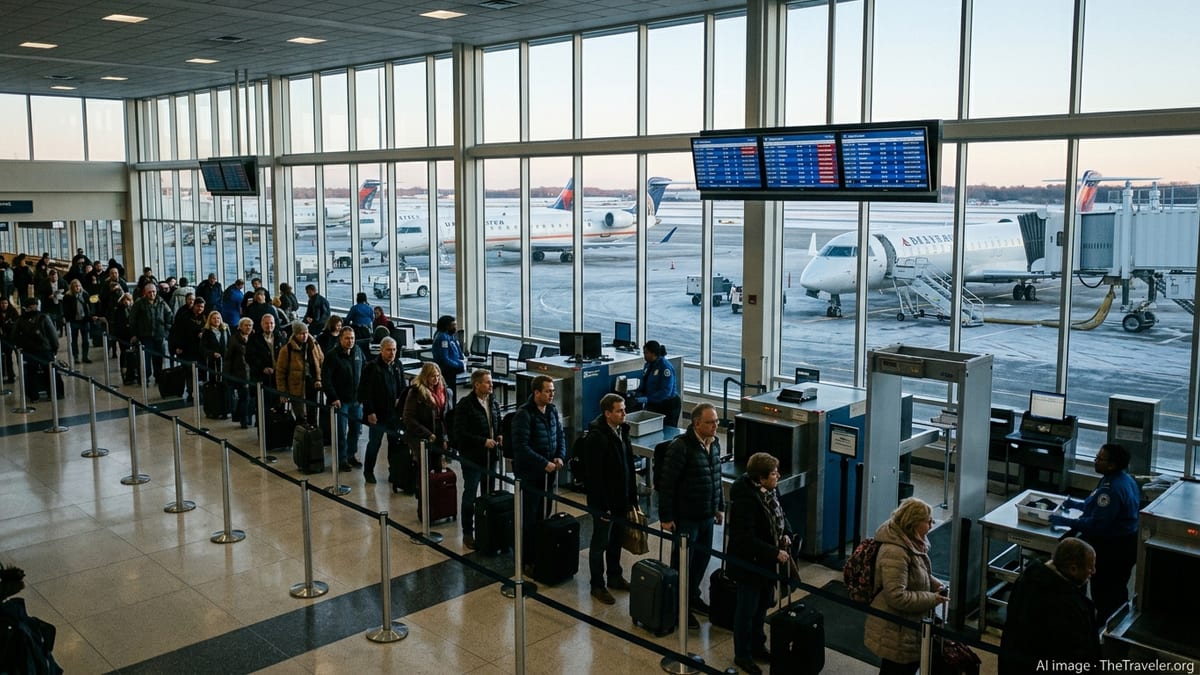
When an air traffic system experiences a technical limitation, the immediate effect is often a reduction in the number of aircraft that can be managed safely in certain airspace sectors. That can translate into regulated departure rates, airborne holding, reroutes, or ground stops, depending on where the issue occurs and how quickly it can be contained.
For travelers, the most visible impacts can include last-minute gate changes, missed connections, and cancellations that occur after aircraft and crews have already been positioned for the day. Because airline schedules are tightly connected, a problem in one morning bank can ripple into afternoon and evening flights even after the technical fault is resolved.
Published coverage around the UK event notes that the disruption took time to clear, reflecting the reality that recovery is not instantaneous. Aircraft and crews end up out of position, airport stands fill up, and pre-planned rotations break, which can force airlines to cancel later services to stabilize operations.
What this means for passengers planning UK travel
For travelers with UK itineraries in the coming weeks, the practical lesson is that even short-lived technical faults can cause prolonged disruption. This is particularly relevant for journeys involving tight connections at major hubs, evening departures that depend on earlier inbound aircraft, or multi-leg itineraries that are harder to re-accommodate.
Travelers who can choose between itineraries may find that nonstop options reduce exposure to cascading delays, and earlier departures can provide more rebooking opportunities later in the same day. Those choices can matter regardless of whether the initiating disruption is weather, airline operations, or air traffic constraints.
In the United States, consumer rules are clear on one core point that often gets overlooked during large disruptions: if an airline cancels a flight and a passenger chooses not to travel, the passenger is entitled to a refund regardless of the reason for the cancellation. That standard does not prevent disruption, but it shapes the financial decision travelers face when rebooking options are limited.
Why the “not operator error” finding is still significant
A finding that the event was not triggered by incorrect actions does not mean the episode was minor, nor does it close the book on accountability. It instead narrows the next questions to engineering controls: what changed in the software, how the defect escaped detection, and whether monitoring tools could have flagged the problem earlier.
It also sharpens the debate about redundancy and resilience in aviation infrastructure. Air traffic systems are built with safety as the overriding priority, which can mean that when anomalies occur, traffic is deliberately throttled to preserve safe separation. That safety-first posture can produce major delays even when there is no safety incident in the conventional sense.
In parallel, the episode highlights the communication challenge during fast-moving disruptions. Publicly available guidance from transportation agencies notes that disruption reasons can be complex and evolve over time, and that definitive causal explanations may require investigation after the fact. For passengers, that can feel like opacity, but for operators it reflects the reality of diagnosing technical events while maintaining safety and restoring service.
What to watch next: reviews, resilience measures, and traveler paperwork
Additional reporting is expected as the UK review process continues and stakeholders assess whether software assurance, testing, or operational fallbacks need changes. For travelers, the near-term impact is less about the technical details than whether new safeguards reduce the odds of a repeat disruption during peak travel periods.
In the meantime, passengers affected by major delays or cancellations often benefit from careful documentation: keeping boarding passes, receipts, and written notice of cancellations can be useful if refunds, chargebacks, or travel-insurance claims become necessary. Consumer guidance in the US also emphasizes that passengers can file complaints with the appropriate federal channels when issues cannot be resolved directly with an airline.
While the report’s early finding points away from operator error, the broader takeaway for travelers is that aviation depends on complex digital infrastructure, and resilience is increasingly as important as raw capacity. Even a brief software defect can become a multi-day scheduling problem, especially when flights, crews, and airport resources are already running close to their limits.