
More news on this day
A preliminary investigation into the UK’s latest air-traffic disruption has concluded the episode was triggered by a software defect and was “not caused by any incorrect actions” by military or civil operators, as fresh scrutiny lands on how resilient the country’s flight-planning systems are during peak travel periods.
Get the latest news straight to your inbox!
What happened during the September 8 disruption
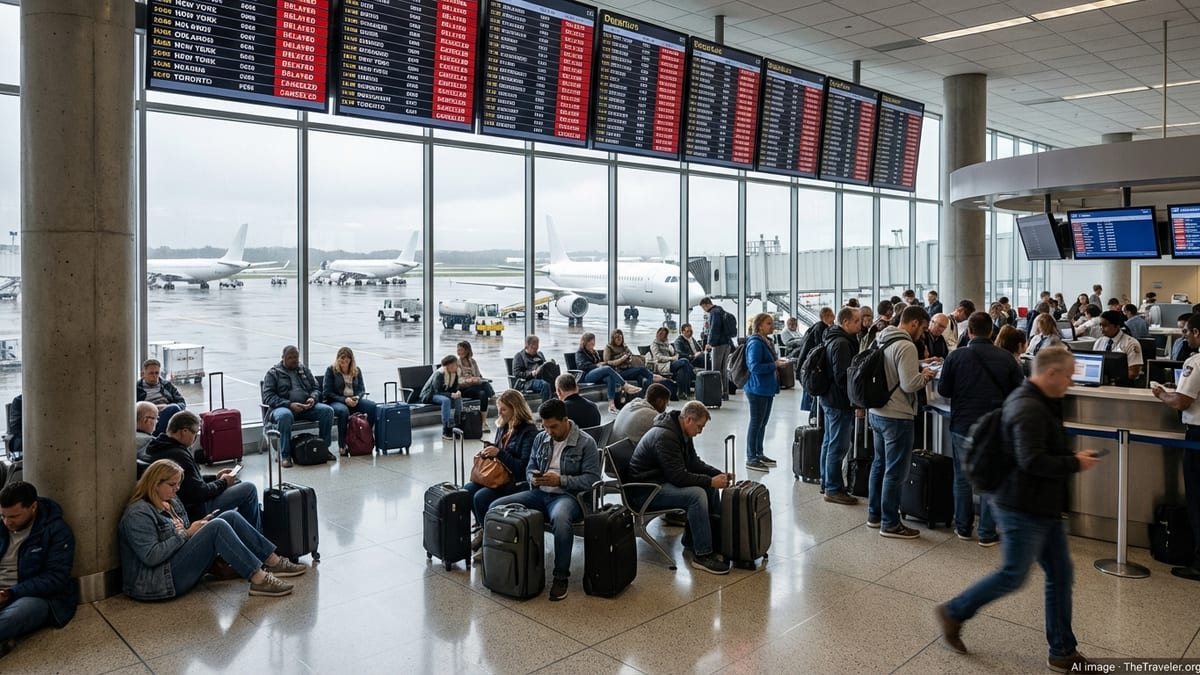
Published coverage indicates the disruption centered on a technical incident affecting National Air Traffic Services (NATS), the main provider of UK air traffic services, prompting restrictions that rippled across airports and airline networks. The knock-on effects included widespread delays and cancellations that took time to unwind, with passengers reporting extended waits in terminals and aircraft holding on the ground as flight plans were managed under tighter constraints.
NATS’ preliminary report describes the trigger as a problem within a specific part of its flight data system. The system supports the management of UK airspace by processing flight data updates that help controllers and airline operations coordinate safe, orderly traffic flows.
According to the report summary released by NATS, the disruption followed a manual request connected to an aircraft code that was being processed when the system received a higher-priority message. When the paused request resumed, the software defect caused it to restart incorrectly, producing corrupted output that then affected subsequent flight data updates.
Why the report says it was not human error
The phrasing that the disruption was not caused by “any incorrect actions” has drawn attention because early speculation in major outages often focuses on whether a wrong input or operational mistake triggered a cascade. The preliminary findings instead frame the issue as a narrow software defect in a small subsection of code, rather than an error by operators entering data or handling traffic.
In the context described, switching between different activities in response to prioritised requests is presented as a normal function of the system. The failure point, as outlined, was the defective behaviour when the paused task resumed, leading to corrupt data and downstream impacts on flight data processing.
The focus on software behaviour matters for travellers because it shapes what happens next: what fixes are required, how quickly they can be tested and deployed, and whether similar conditions could reappear. It also influences regulatory and political discussions about technology governance and investment, particularly when the disruption is described as avoidable through better detection or resilience planning rather than changes to frontline operational practices.
Regulatory scrutiny and the next reports due
Publicly available information shows the UK government requested a report into the incident and asked the UK Civil Aviation Authority (CAA) to carry out an independent review. The CAA process is expected to examine what happened, how NATS is set up to deliver a resilient service, and what improvements may be needed.
That independent review timeline means travellers may see an initial technical explanation now, with a longer tail of recommendations later. In practice, the near-term steps typically involve verifying the defect, confirming mitigations, and validating that monitoring systems can flag early warning signs before disruption spreads. The longer-term steps can include software assurance, change-management controls, backup procedures, and capacity for operating in degraded modes with fewer knock-on cancellations.
For passengers, the key point is that the preliminary report does not close the matter. The independent review adds a second layer of scrutiny, and the aviation system’s performance during disruption, including communications and recovery, can be part of how regulators and policymakers judge whether resilience targets are being met.
What disrupted travellers should know about refunds and compensation
Passenger entitlements depend on where the trip took place and which rules apply. In the UK and EU-style frameworks, compensation for delays or cancellations can hinge on whether an event is considered an “extraordinary circumstance.” Published CAA guidance around the September 8 NATS disruption has indicated the outage is likely to fall into that category, which can affect compensation eligibility, even though other duties such as care and rerouting can still apply depending on the situation.
Separate from compensation, travellers often have clearer rights around refunds when they choose not to travel after a cancellation. For example, in the United States, Department of Transportation rules and guidance emphasize that if an airline cancels a flight and a passenger does not accept alternatives, a refund is owed regardless of the reason for the cancellation. That distinction is important for Americans caught in transatlantic knock-on disruptions, even when the original trigger is outside airline control.
Because airline policies and legal regimes vary by itinerary, travellers affected by the UK disruption have generally needed to look at the operating carrier, where the flight departed from, and whether the ticket was issued under conditions that place the itinerary under UK/EU passenger-rights rules or under US DOT refund expectations. When the disruption cause is technical and systemwide, rebooking timelines can also stretch as aircraft and crews end up out of position, making early proactive rebooking decisions more valuable.
Why a “small” software defect can have a big aviation impact
Modern airspace management relies on interconnected software that transforms flight plan inputs and updates into an operational picture used by controllers and airline network teams. A defect affecting how flight data updates are processed can force conservative restrictions, even when safety is not compromised, because the system’s ability to reliably track and sequence traffic becomes constrained.
The preliminary description of a millisecond-scale exposure window highlights a broader theme in critical infrastructure: rare timing conditions can sit undetected for long periods and only surface when a precise set of events occurs. That creates pressure for stronger testing, better simulation of edge cases, and more robust monitoring that can detect data corruption early.
For travellers, the practical lesson is that technology incidents can produce disruption that looks similar to weather or staffing problems but behaves differently in recovery. When a central system issue triggers capacity restrictions, airlines may have limited options until airspace flow is normalized, and the backlog can persist through later departures as networks re-sync. That reality is likely to keep resilience and redundancy high on the agenda as regulators review the September 8 incident and the industry heads into its next high-demand travel stretch.