
More news on this day
A preliminary investigation has attributed a wave of UK flight disruption earlier this month to a software defect that unfolded in a window measured in milliseconds, triggering corrupted flight-data outputs and cascading operational restrictions that took days to unwind.
Get the latest news straight to your inbox!
What the preliminary report says happened
Published coverage indicates the incident centered on a component of the UK’s National Airspace System used to allocate aircraft codes that help identify flights on radar and support routine flight-data updates. The preliminary report describes a sequence in which a valid, manual request for an aircraft code was interrupted by another request, briefly pausing processing.
When the system resumed, the software defect meant processing did not restart correctly. According to the preliminary report, the resulting output became corrupted and affected subsequent flight data updates, leaving controllers without access to some live flight data and prompting the use of established fallback procedures while safety margins were maintained.
While the underlying fault occurred quickly, the broader impact reflected the complexity of safely restarting and managing capacity across a national airspace network. The preliminary report frames the disruption as an internal technical failure rather than an external interference event.
How disruption spread across airports and airlines
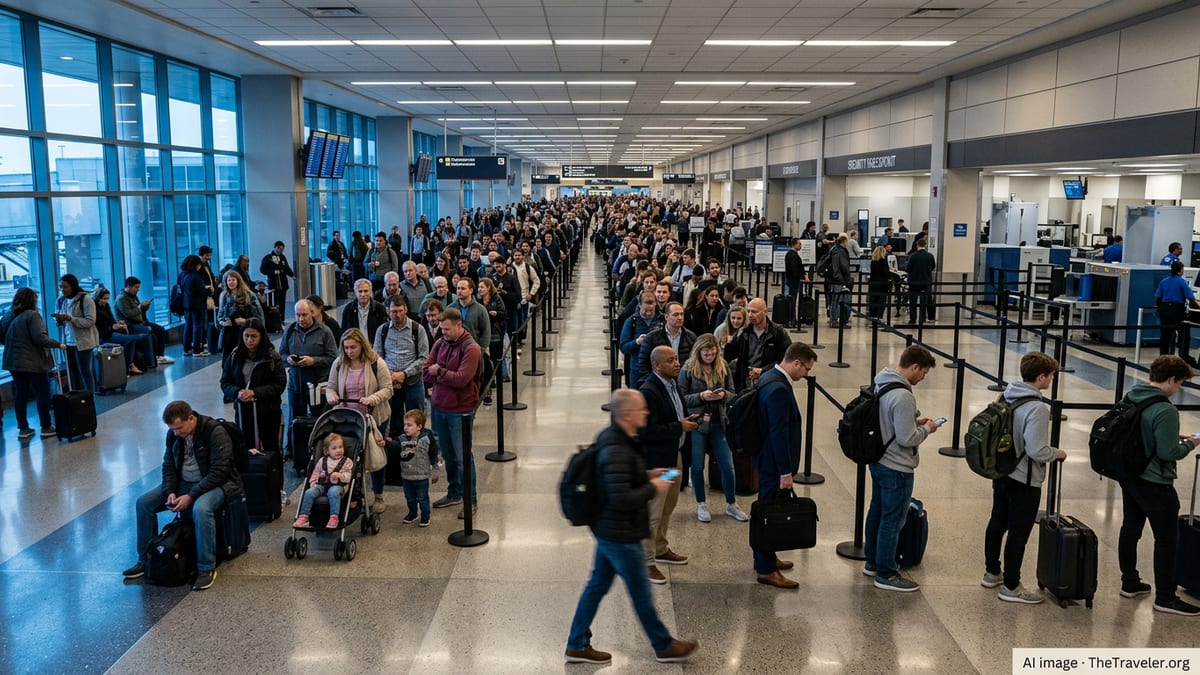
Reports describe widespread knock-on effects for passengers and airlines, with more than 2,000 flights cancelled in and out of the UK following the technical incident, along with additional delays and diversions. Coverage characterized the disruption as affecting hundreds of thousands of travelers, as airlines worked through aircraft positioning, crew scheduling limits, and airport stand constraints.
The disruption was not limited to a single terminal or carrier. When air traffic flow restrictions are imposed to keep operations safe while systems are stabilized, airports can quickly develop backlogs that persist long after the original technical problem is resolved, particularly when cancellations strand aircraft and crews away from their next scheduled sectors.
For travelers, the most visible consequences were long waits, last-minute cancellations, missed connections, and difficulty rebooking during peak periods. Published accounts also noted that even after traffic restrictions lifted, airlines and airports faced a multi-day recovery to return to normal schedules.
Why a “millisecond” defect matters for critical aviation systems
The “millisecond” framing in coverage underscores how rare timing-dependent defects can evade routine detection until an unusual sequence occurs in live operations. The preliminary report’s narrative suggests the fault could remain hidden unless a narrow set of conditions aligned, raising questions about testing for edge-case concurrency and recovery behavior, not just normal processing.
Aviation systems are built around layered safeguards, so a technology fault does not automatically translate into unsafe aircraft separation. In this episode, reports emphasize that fallback procedures were used when controllers lost access to some live flight data, prioritizing safety by reducing the volume of traffic that could be handled while the system state was confirmed and restored.
Even so, the event illustrates a broader industry tension: resilience is not only about preventing failures, but also about limiting disruption when failures occur. In practice, that can mean designing systems and operational playbooks so that a localized defect does not require wide restrictions, and so that recovery does not create secondary issues that prolong passenger disruption.
Accountability, resilience, and what may come next
The preliminary findings have renewed scrutiny of the UK’s air traffic infrastructure and its ability to withstand unexpected software faults without nationwide ripple effects. Coverage indicates the incident is being treated as distinct from earlier disruptions in recent years, with the report describing a specific coding subsection as the root of this month’s failure mode.
For airlines, the episode also reopens a familiar debate about where disruption costs should land when airspace constraints or air traffic technical incidents lead to mass cancellations. In the UK and Europe, passenger rights frameworks can require airlines to provide care such as meals, accommodation, and rerouting in many scenarios, though cash compensation rules can vary depending on whether an event is considered outside an airline’s control and on the specific circumstances of a delay or cancellation.
For travelers affected by this month’s disruption, the practical next steps remain documentation and persistence: saving notices of cancellation, receipts for eligible expenses, and records of rerouting offers. The investigation’s next phase is expected to sharpen what the defect was, how it escaped detection, and what engineering and operational changes are planned to reduce the chance that a brief software fault can again escalate into multi-day air travel disruption.